Data Platforms
Northstar
Cloud architecture, ingestion, transformation, orchestration, security, infrastructure, and operational data engineering.
Projects
My engineering work spans cloud data platforms, analytics, enterprise data systems, backend development, integrations, and independent software products. Together, these projects show different parts of the same approach: understand the domain, model the problem carefully, automate what should be repeatable, and build systems that remain understandable when the real world gets complicated.
Data Platforms
Cloud architecture, ingestion, transformation, orchestration, security, infrastructure, and operational data engineering.
Product Engineering
Application architecture, domain modeling, workflow design, offline reliability, and end-to-end product development.
Backend, Analytics & Automation
Java backend engineering, reusable analytics, diagnostics, data quality, integration, and workflow automation.
Enterprise Data & Analytics
Oracle PL/SQL, analytics, enterprise data, production support, and business-to-technical translation.
A production-style AWS data engineering platform built around a synthetic outdoor-retail company. Northstar is being developed incrementally to demonstrate the lifecycle of a modern data platform rather than a collection of isolated tutorials or disconnected service demos.
What this demonstrates
Hands-on cloud and data-platform engineering, architecture, pipeline design, data quality, testing, observability, security, infrastructure as code, and the ability to explain and defend technical decisions as the platform develops.
Target Platform Scope
The architecture is being implemented in stages. The target platform includes:
Independent Software
Independent product work introduces a different engineering constraint: instead of solving only the technical problem, I also have to decide what the product should do, how users should understand it, how the domain should be modeled, and which complexity should never reach the user.
An offline-first field-service application designed for owner-operators and small service businesses. ShimStack connects estimating, jobs, visits, scheduling, materials, purchasing, expenses, payments, and business financial planning in one operational workflow.
What this demonstrates
Product architecture, domain modeling, application development, offline-first design, and the ability to turn complicated real-world workflows into understandable software.
Engineering Highlights
Product Screens
These screens show several of the core operational areas of the application as they currently exist during active product development.
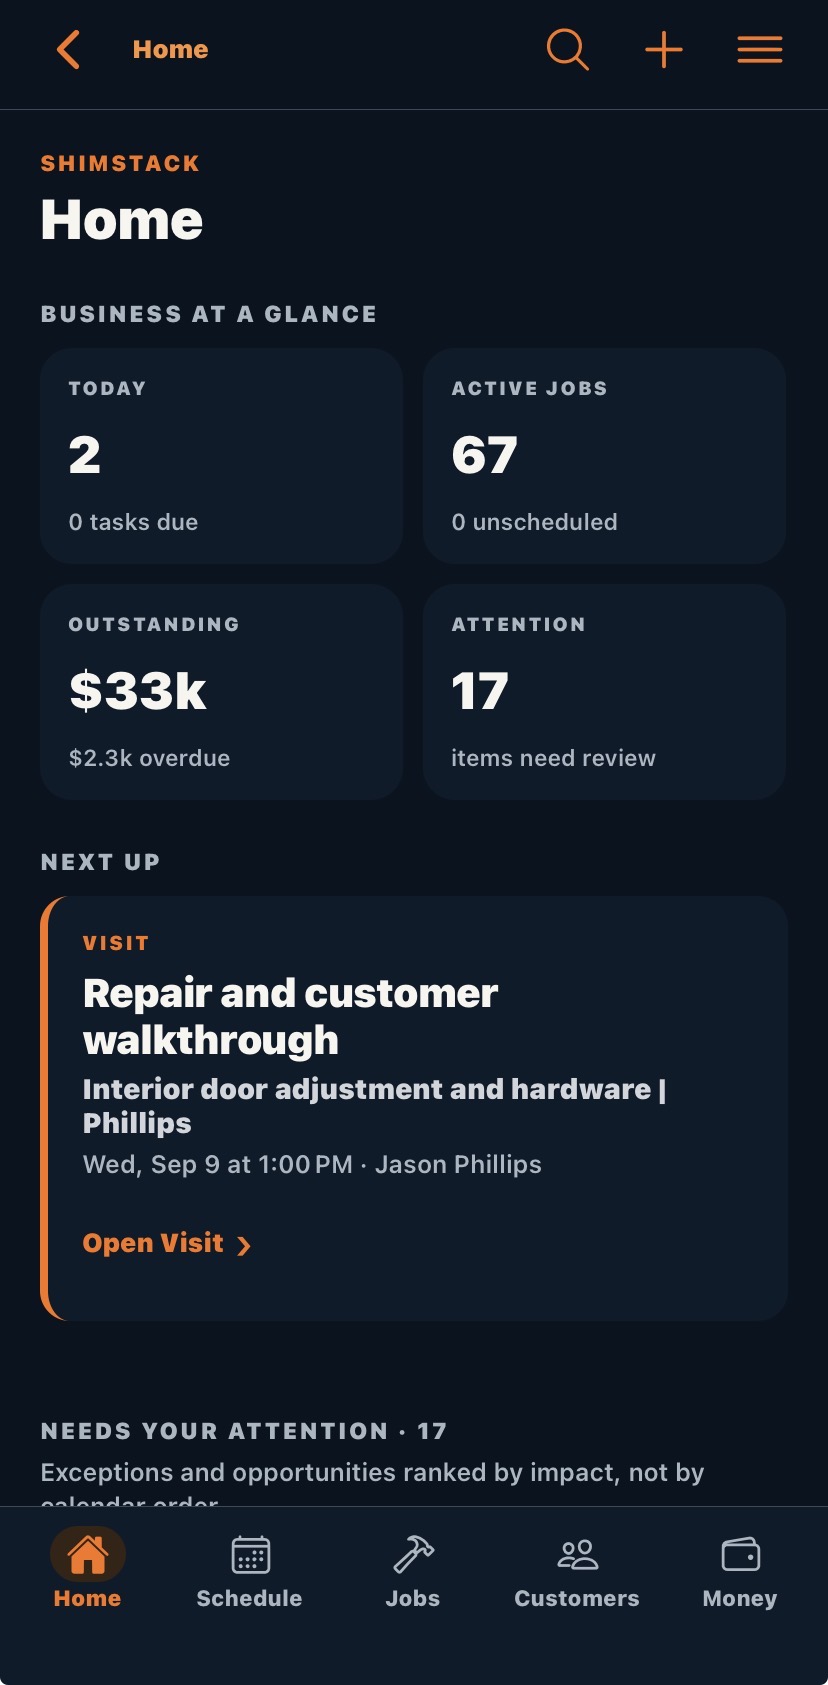
Home
Daily work, attention items, and upcoming activity.
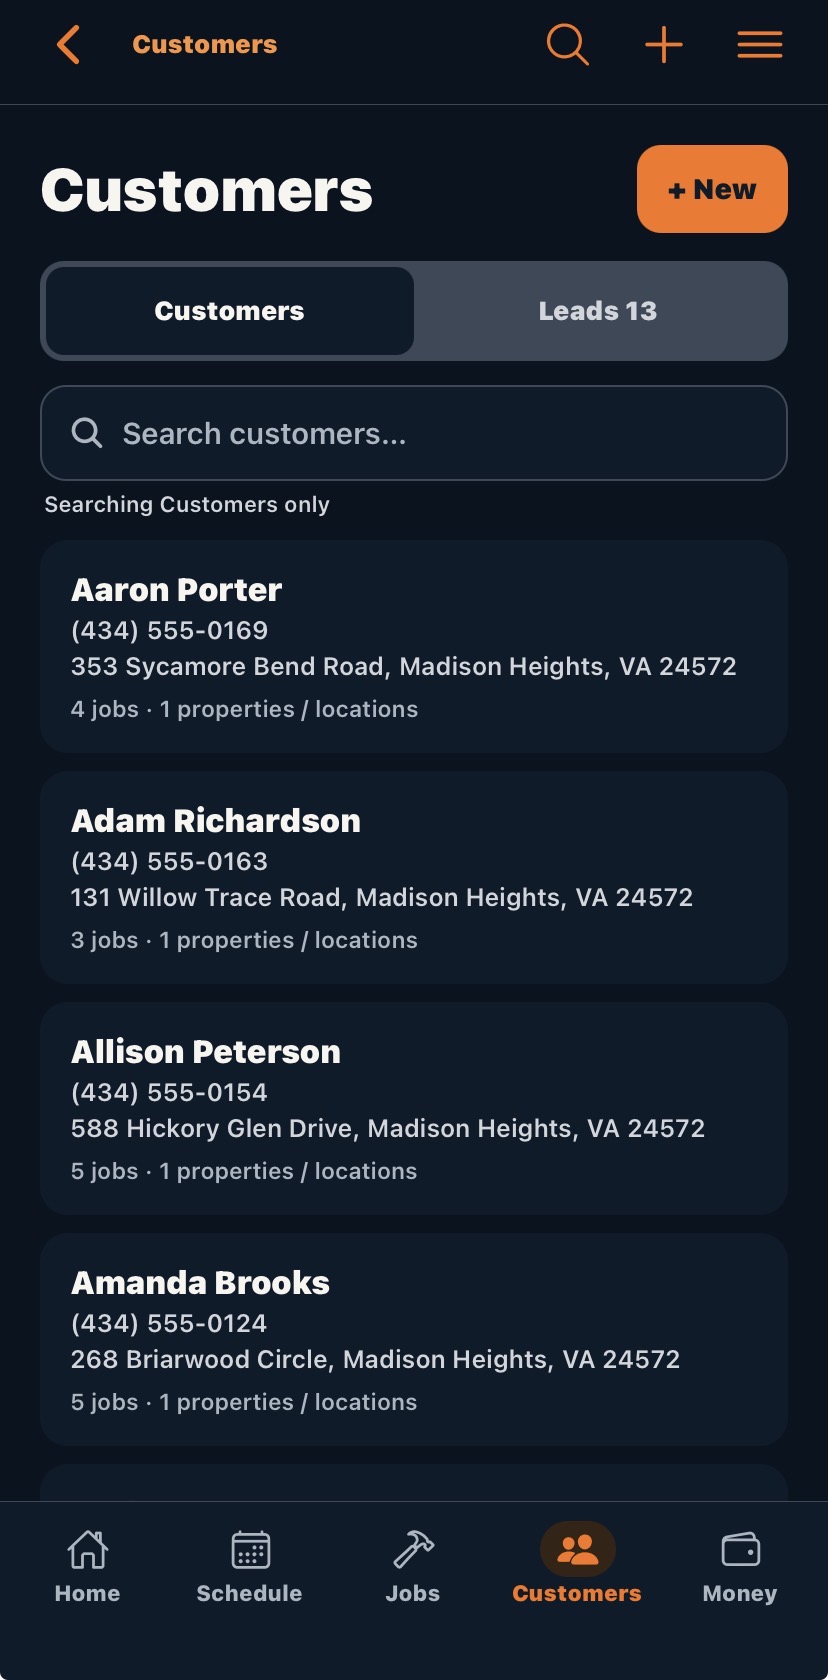
Customers
Customer records and the starting point for client work.
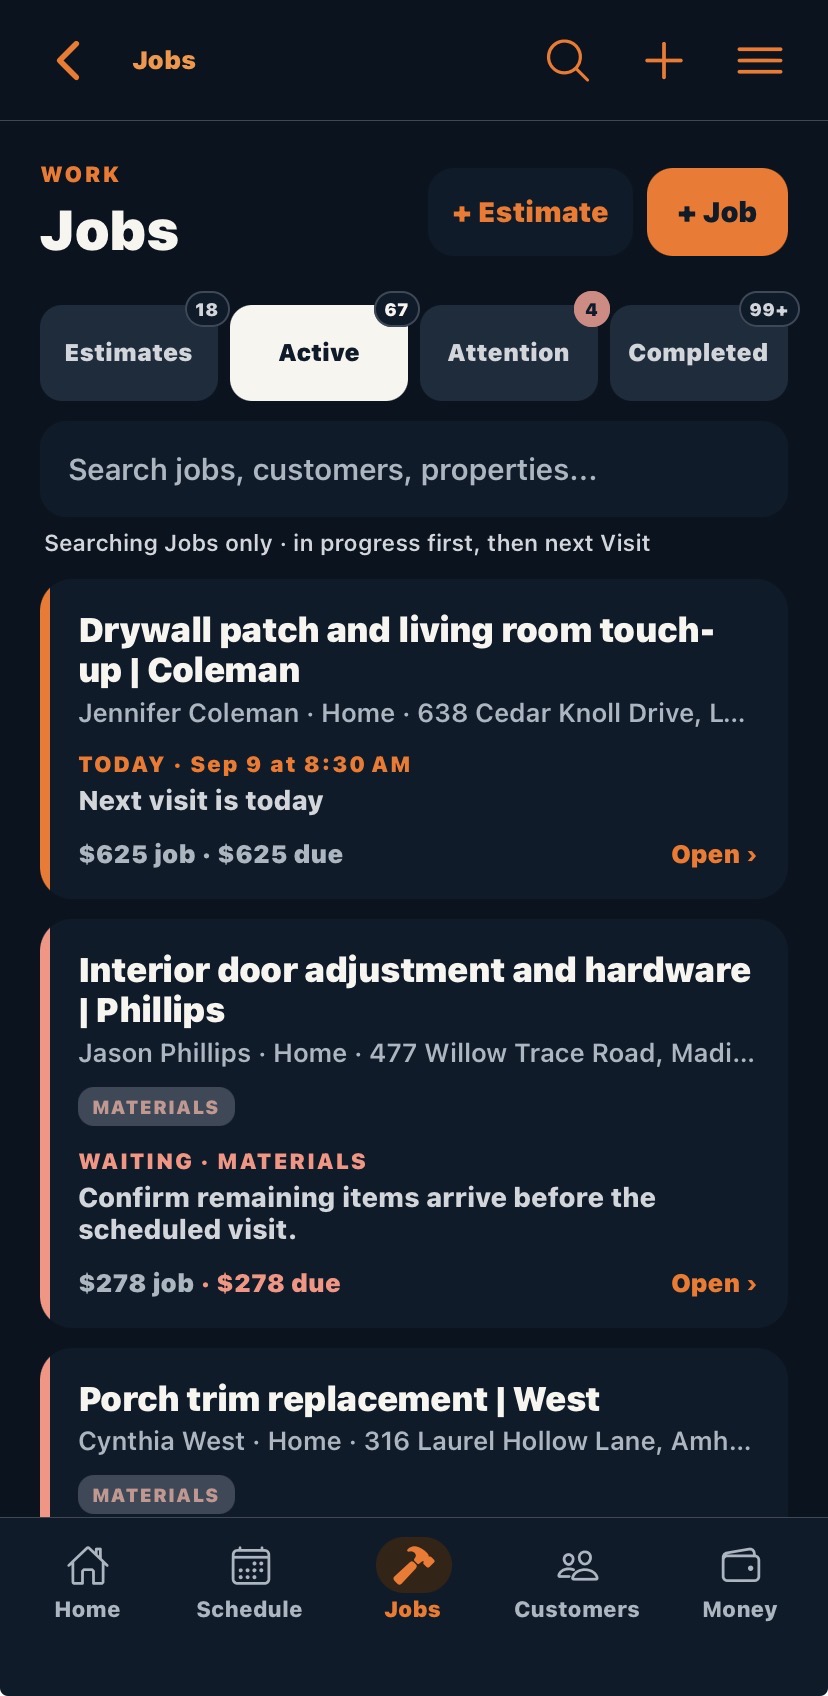
Jobs
Active work, project status, and field-service operations.
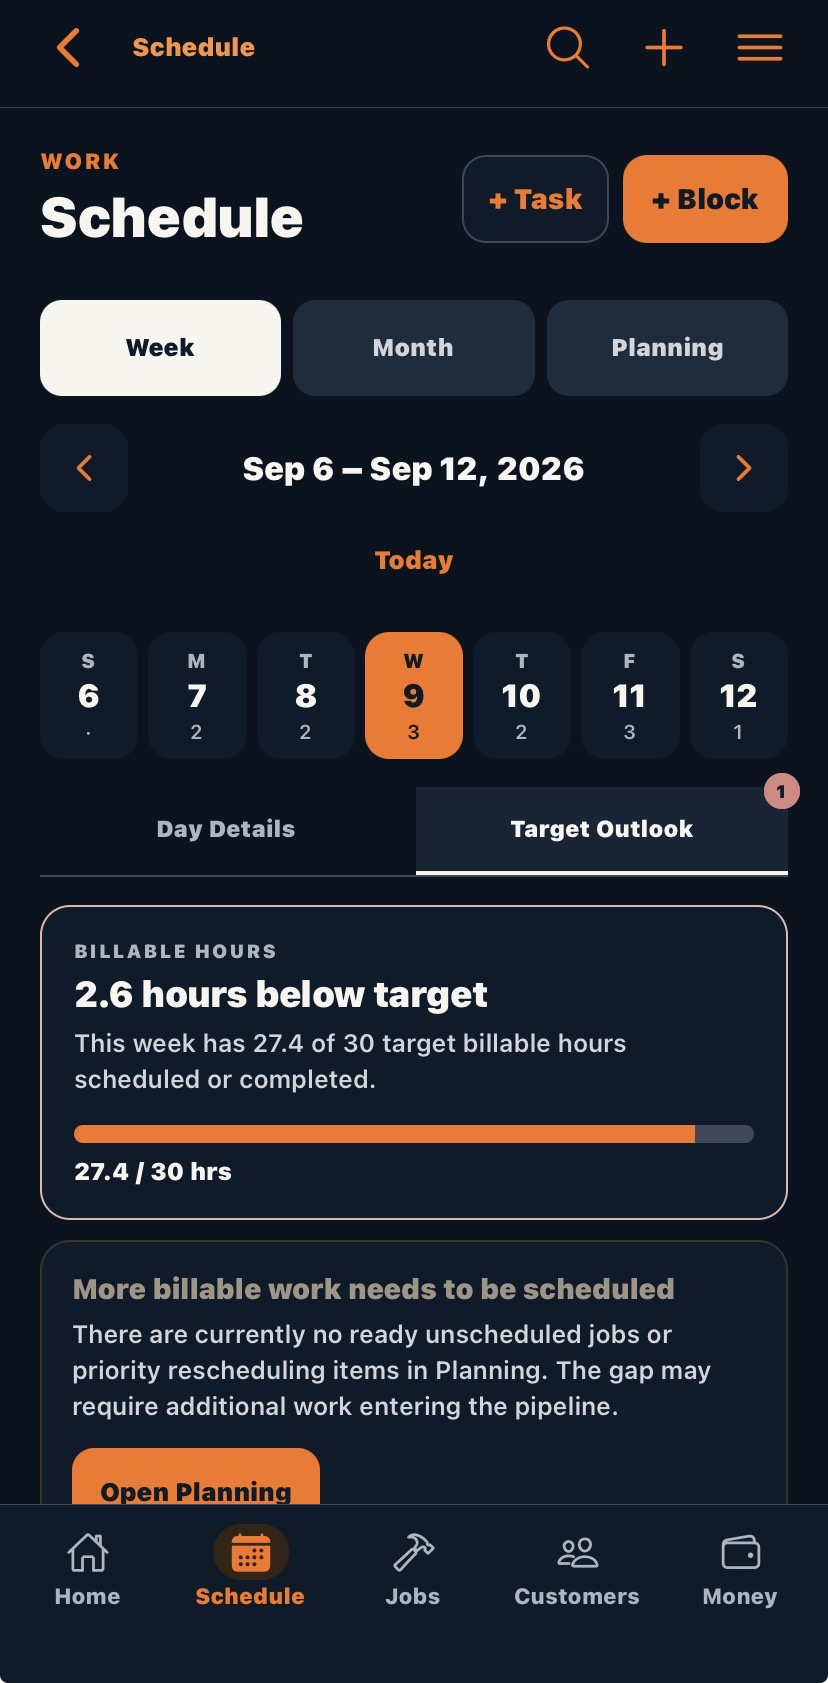
Schedule
Planning visits and managing upcoming workload.
Professional Engineering
These systems were developed as part of my professional work. Proprietary source code, customer information, and internal data are not published here. The descriptions instead focus on my engineering role, technical responsibilities, architecture, and the problems each system addressed.
A Java-backed internal analytics, reporting, diagnostic, and data-quality platform built to support ERP consulting engagements. Nessie processed enterprise data and produced structured JSON outputs that were consumed by a vanilla JavaScript frontend to generate a static analytics site refreshed daily. The interface surfaced financial, project-performance, configuration, compliance, and data-quality findings and allowed users to generate preformatted remediation files compatible with Unanet's import functionality.
What this demonstrates
Backend and frontend software engineering, analytics engineering, enterprise data integration, reusable tooling, automated data-quality workflows, JSON-based application architecture, technical ownership, and engineering for measurable business impact.
Engineering Highlights
A centralized marketing data application built on Ellucian Banner data to generate, manage, and deliver institutional marketing audiences and reporting datasets.
What this demonstrates
SQL and PL/SQL engineering, analytics, product ownership, enterprise-data expertise, production support, and translating business requirements into maintainable data-system behavior.
Engineering Highlights
The Common Thread
Northstar, ShimStack, Nessie, and Centralist solve very different problems, but they reflect the same way I tend to approach engineering: understand the domain before designing the system, identify where the real complexity lives, and make that complexity manageable through clear models and repeatable processes.
I care about correctness, traceability, maintainability, and explainability because most difficult technical problems do not stay confined to one query, service, application, integration, or team.
That perspective comes from working across both sides of enterprise technology: years of understanding business processes and users, followed by progressively deeper work with the data, analytics, software, integrations, and infrastructure behind them.